-
Auto-contextualization, Not Attention
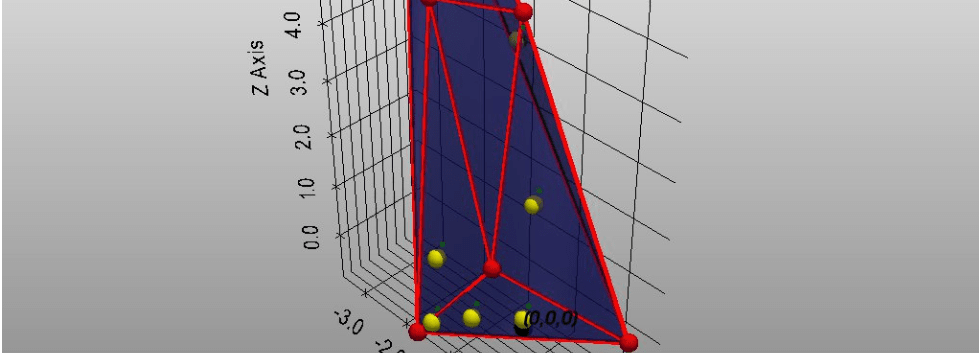
A computational geometric perspective on the elegant phenomenon behind GPT like, BERT like large language models and what makes them so powerful.
I blog about deep learning, reinforcement learning, machine learning, mathematics and computer science.
A computational geometric perspective on the elegant phenomenon behind GPT like, BERT like large language models and what makes them so powerful.

